// Chaos & Reliability Engineering Services
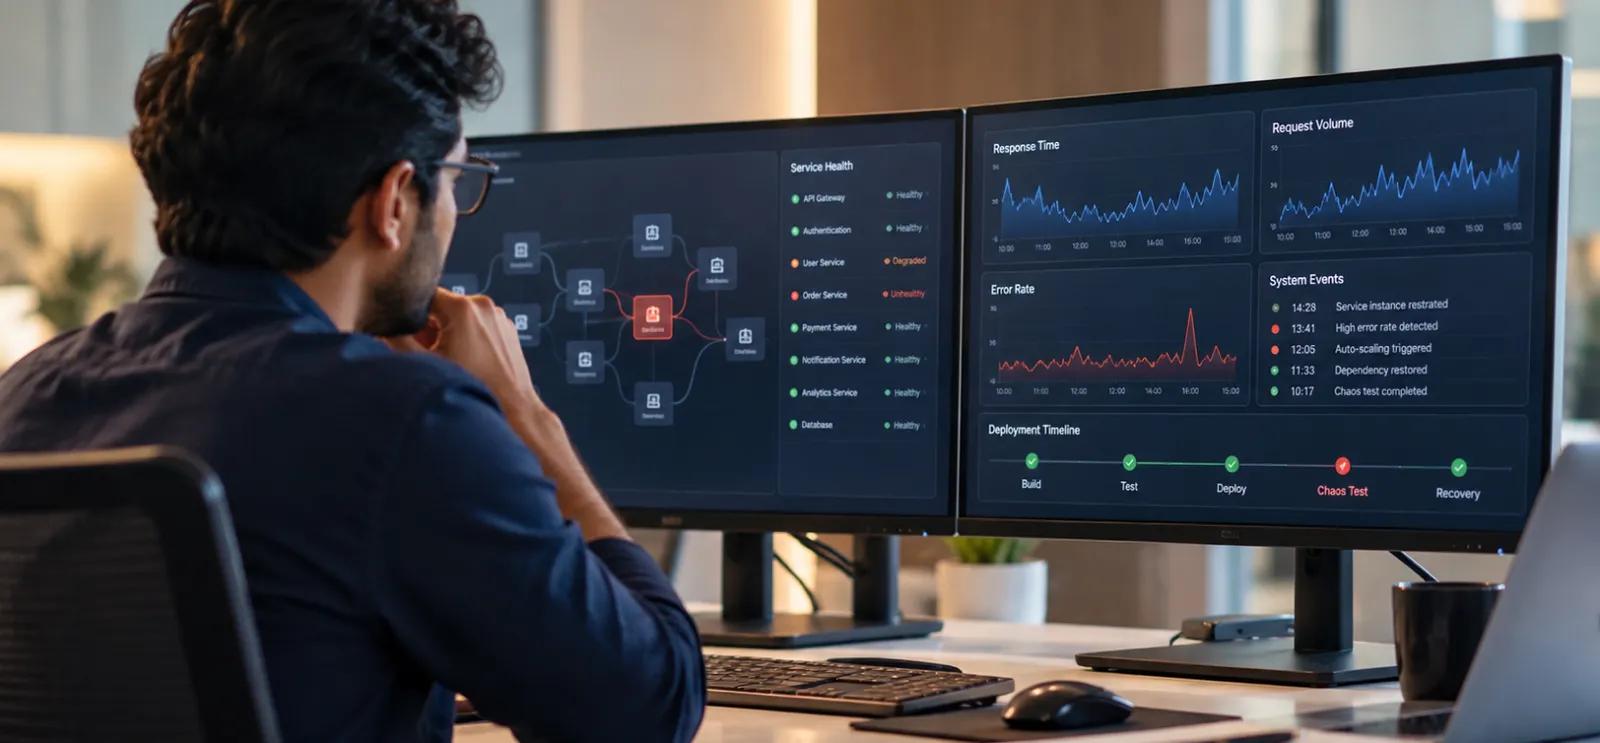
// Why "It Works in Dev" Isn't Enough
Hidden Single Points of Failure
A dependency that's always been up has never been tested for absence. Redundancy is theoretical until proven under controlled failure.
Cascading Failure Blindspot
Circuit breakers exist but are rarely validated under realistic load, so a single API timeout cascades into a full outage.
Recovery Path Assumptions
Teams assume a 30-second failover because the documentation says so. Nobody has measured the actual recovery time.
Our chaos engineering services inject failure on purpose, before an incident forces the experiment on you.
// Jignect's Chaos Engineering Capabilities
Infrastructure Fault Injection
Instance termination and pod deletion validate that your infrastructure isolates applications from compute failures.
Network Chaos
Latency injection, packet loss, and partitions simulate real-world WAN conditions and validate your timeouts.
Database Failure Simulation
Primary failover and connection pool exhaustion test the exact recovery path your applications will actually take.
GameDay Design & Facilitation
Full-day simulated incidents that validate observability, playbooks, and team muscle memory before a real one hits.
// Chaos Engineering Tool Ecosystem
// Deliverables, Not Just an Experiment Log
Dependency Map & Failure Analysis
A clear picture of your architecture's real single points of failure.
Designed Chaos Experiments
5 to 10 experiments with hypothesis statements, from staging through to production.
Resilience Report
A detailed report on the gaps discovered, with severity and business impact.
Reliability Roadmap & Runbooks
A prioritized plan and runbooks your on-call team can actually use.
// Failure Is Inevitable. Being Unprepared Isn't.
// Latest Articles.
// Questions, Answered.
Who is Chaos Engineering built for?
It's built for teams whose redundancy has never been tested under real failure; teams whose circuit breakers have never been validated under load; teams assuming a recovery time without ever having measured it; and teams running SLOs without knowing what burns the error budget fastest.
Is chaos engineering safe to run in production?
Yes, when designed correctly. We start in staging, validate rollback mechanisms, begin with a small blast radius, and keep kill switches armed throughout every experiment.
What's a GameDay and why does it matter?
A GameDay is a full-day, coordinated incident simulation that validates observability, incident response playbooks, and team coordination, so a real incident gets a faster, more confident response.
How do you define the blast radius of an experiment?
Blast radius is the boundary of impact. We always test in layers, starting small and scaling up only once impact is measured, never injecting chaos at full radius on the first experiment.
Which chaos tools do you use and why?
Tool choice depends on your stack. LitmusChaos and Chaos Mesh for Kubernetes, Gremlin and AWS FIS for multi-cloud, and tc/netem or Toxiproxy for network chaos, recommended by architecture, not preference.
How does chaos engineering relate to SLOs and error budgets?
Chaos engineering measures which faults burn your error budget fastest, turning a stated SLO into a concrete, prioritized list of reliability fixes.
What does a chaos engineering engagement deliver?
A dependency map and failure mode analysis, designed experiments with hypotheses, staging and production execution results, a resilience report, a prioritized roadmap, and runbooks for detected failure modes.